This is a reading guide to the Engineering Evidence Review, the version of the Governance in use record written for AI engineers and technical evaluators. It is a public work in progress, with evidence through 9 October 2026.
Read the Governance in Use — Engineering Evidence Review
The proposition
A human-led agent system is being used to govern its own improvement while development continues. The review does not ask a reader to accept that the system works. It puts a narrower question: do the selected records support their specific claims, and what further tests would establish repeatability and enforcement?
The underlying story
The operator wanted the work itself to be inspectable: what the task was, which agent was investigating it, what another agent challenged, what needed a person's decision and what stayed unresolved. The goal was not to make every technical gap disappear before presenting the proof of concept.
An agent first pursued technical completion beyond that goal. The person corrected the scope, and the records kept both the correction and the unfinished engineering. Two linked records carry the two outcomes. One holds the work's gap, diagnosis, remedy and acceptance. The other holds the walkthrough, communication landmarks and capture evidence. Capturing an operation and preparing a write-up does not install a repair or close the technical task behind it.
The central case: review changed a proposal before implementation
On 9 October, preparation for a new correction experiment exposed missing source bindings for three existing functions. The operating agent investigated and proposed three import corrections and the matching source mappings.
The reviewing agent tested isolated copies and accepted the three edits with conditions. It corrected the mapping and the write procedure, and it found fourteen affected imports rather than three. Later review removed a circular requirement, required audit events to refer to a real task, and set out six ordered checks for obtaining that task. Nothing was executed.
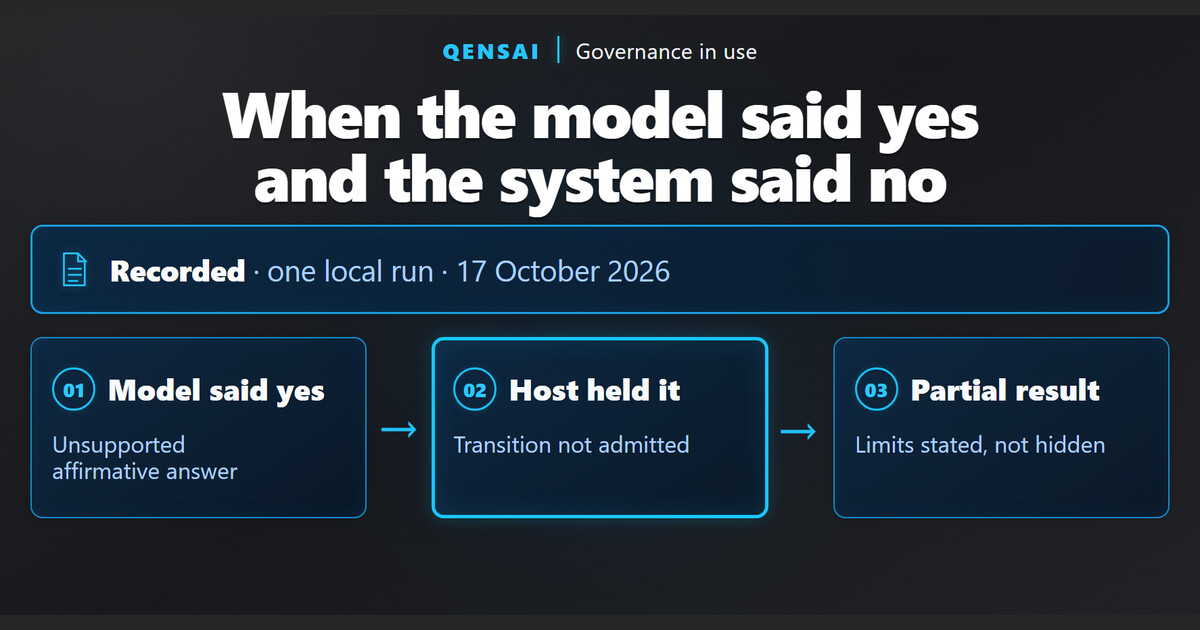
At the last readback, the operator's decision row was still pending and unanswered. The reviewer's acceptance was not treated as permission to implement. A separate attempt to link a task to a gap record was refused because it needed an administrator. That is one observed refusal, not a complete security test.
The review's conclusion is bounded: the record supports inspectable challenge, revised conditions and a separate human decision. It does not establish that the proposed repairs were installed, and the new correction experiment remained open.
Six supporting cases, each on its own terms
- 28–29 September. A real defect became a reviewed product fix. A selected task disappeared on reload. The owning seat traced a repair through commit, deployment and hosted owner-view checks. Scoped to the owner view.
- 30 September. Approval, completion and capture were correlated. A recorded sequence: human approval, completion 21 seconds later, and automatic capture one second after that. One local example; the timestamps show order, not a speed claim.
- 2 October. Three seats answered on one work surface. A person sent and armed one read-only request per seat; each answer came back to the Response Table. One trial per seat on one workstation, with a known watcher error still open.
- 7 October. An inaccurate answer was kept and challenged. The first answer invented terminology and was rejected. A revised request produced a better answer that still had gaps. Because the request changed, this is not a controlled same-prompt experiment.
- 15 September. An approved correction changed the rendered output. A separately approved correction added explanation and alternatives to a terse refusal. The raw model answer stayed terse: this is application rendering, not model learning.
- 15 September. A held task took one approved change. The task was held, one correction was approved, the held response was reused, and the recorded chain shows one model dispatch. A different task from the case above; not a cost or latency result. An earlier failed attempt stays on the record.
Intended controls versus observed instances
The review lines up each part of the design with what the records actually contribute and what would verify it next: request intake and identity, the governing rules for a task, threaded correspondence, the Response Table and human decisions, feedback, and capture. The records supply single dated instances. They do not show that every mechanism ran in every case.
What is supported, and what is not
- Supported now: dated examples of human-led work, concrete agent challenge, saved communication and decisions, retained failures, correction provenance and source-linked capture.
- Still open: the new correction experiment, the proposed repair installation, remaining engineering gaps and separately recorded operator decisions.
- Needs new evidence: repeatable enforcement, full permission coverage, independently attested model execution, production reliability, savings, and physical robotic control.
A proposed evaluation, not a result
The review ends with six tests an independent evaluator could run: authority before action, threaded correspondence, an approved correction pair, a held checkpoint, proposal promotion and capture integrity. Each lists what to freeze beforehand and what evidence would count. None of them has been run for this review. Failed trials should be kept, and rates reported only when actually measured.
The review links its sources: the full process account, two evidence annexes with machine-readable records, and package checksums. Those sources are redacted; private originals stay with the operator. Checksums identify bytes. They do not by themselves establish that an event happened.
The plain-language version of the same story: One Request, Governed
Read the full Engineering Evidence Review
0 comments